Project: In 2008, Flickr was one of the most popular photo-sharing platforms on the internet. Their engineering dashboard tracked a metric the team was proud of: lines of code committed per week. Engineers competed informally to top the leaderboard.
And gradually, the codebase became bloated with unnecessary features, redundant implementations, and code written to boost the metric rather than to solve user problems.
Meanwhile, a small startup called Instagram launched in 2010 with a tiny codebase, focused on a single metric - daily active users - and within 18 months had more users than Flickr had ever achieved.
The Flickr story is a vivid illustration of Goodhart's Law, attributed to British economist Charles Goodhart and popularized in the 1990s: "When a measure becomes a target, it ceases to be a good measure." The insight is not that metrics are useless.[3]
It is that metrics must be selected to measure outcomes, not outputs - and that when a metric can be gamed, it will be gamed.[6]
Project metrics are the instruments through which project health is understood and managed.[8] Used well, they provide early warning of problems, quantify progress, and support decisions about resource allocation, scope, and schedule.
Used poorly, they produce false confidence, misaligned incentives, and the displacement of substantive work by metric optimization.
"When a measure becomes a target, it ceases to be a good measure." - Charles Goodhart. The practical corollary for project managers: track the metric that reflects health, not the metric that is easiest to improve.
| Metric Category | What It Answers | Leading or Lagging | Example Metrics |
|---|---|---|---|
| Schedule and velocity | Are we on track? | Leading (velocity trend); lagging (schedule variance) | Sprint velocity, burn-down, schedule variance (SV) |
| Quality | Are we building it correctly? | Both | Defect rate (lagging); test coverage (leading) |
| Scope and requirements | Is the definition stable? | Leading | Scope change rate; requirements approval backlog |
| Team health | Is the team sustainable? | Leading | Blocker age; cycle time per task; unplanned work ratio |
| Stakeholder satisfaction | Are we delivering what stakeholders need? | Lagging | Net Promoter Score; sponsor satisfaction; acceptance rate |
The Leading-Lagging Distinction
The most important structural distinction in project metrics is between leading indicators and lagging indicators.
Lagging indicators measure outcomes that have already occurred. Defect rate, cost variance, schedule variance, and customer satisfaction scores are lagging indicators - they tell you how you have done. They are accurate and objective but provide information after the fact, when options for correction have narrowed.
Leading indicators measure predictors of future outcomes. Velocity trend (is the team getting faster or slower?), blocker age (how long has the critical path been blocked?), and scope change rate (how frequently are requirements changing?) are leading indicators - they tell you where you are going before you get there.
They are less precise than lagging indicators but more actionable.
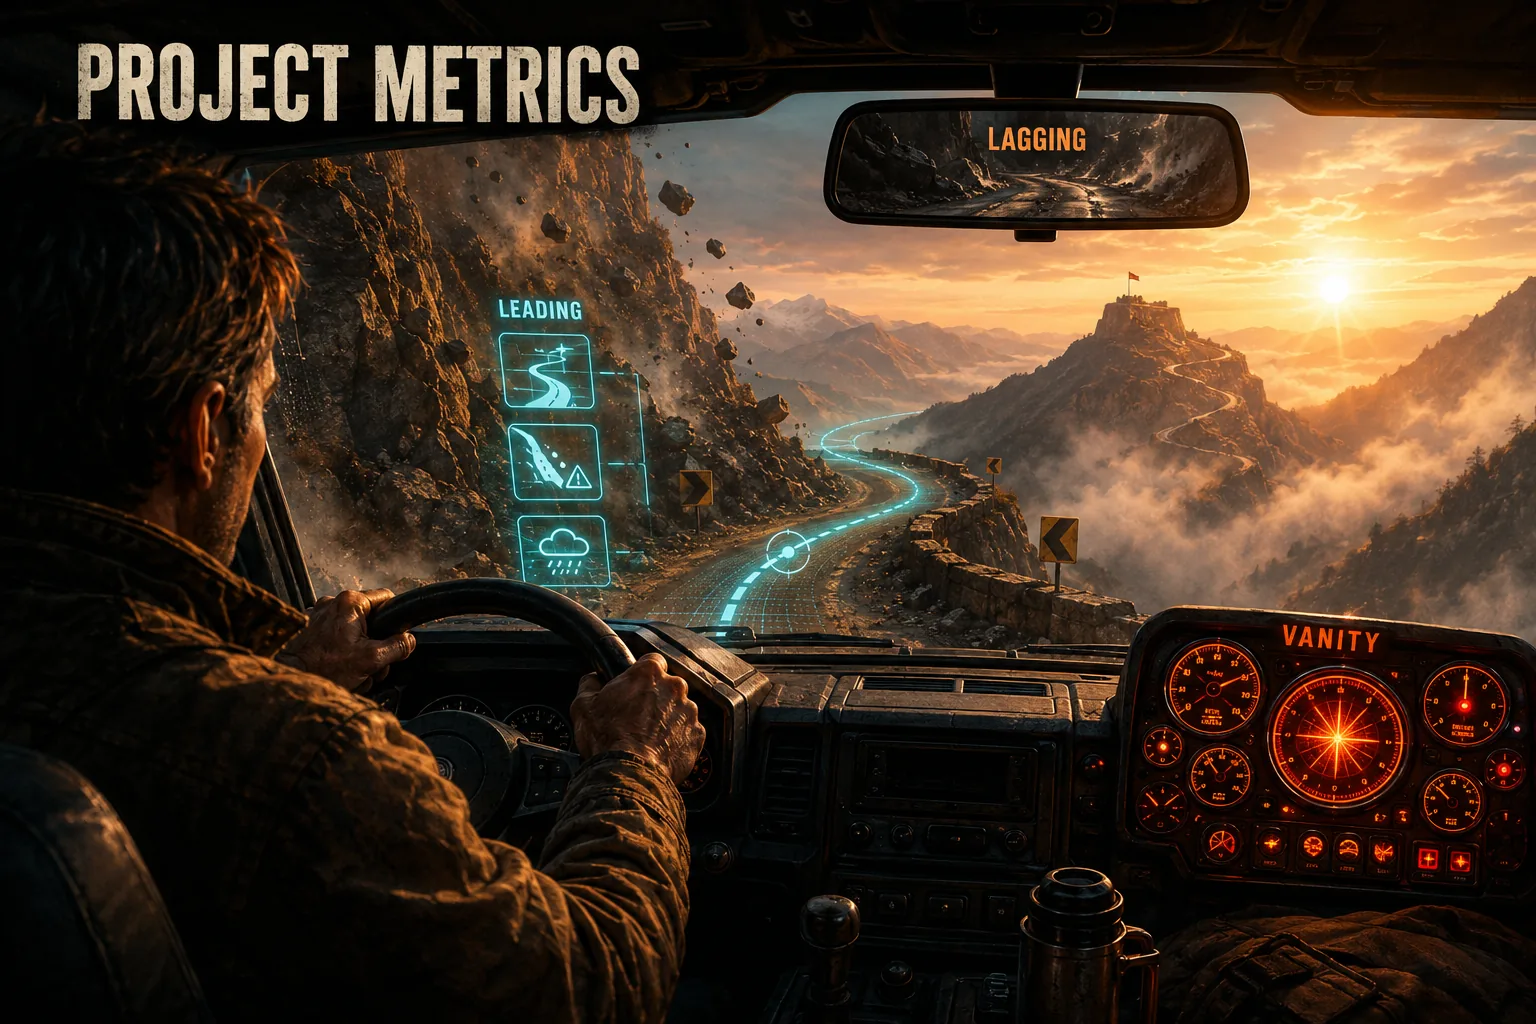
The practical implication: project dashboards should be dominated by leading indicators during active execution and by lagging indicators during retrospectives and post-mortem analysis. A project dashboard showing primarily lagging indicators is a rearview mirror - useful for learning, but not for steering.
Example: Google's DORA (DevOps Research and Assessment) metrics, developed through research by Nicole Forsgren, Jez Humble, and Gene Kim, identify four leading indicators of software delivery performance:[1]
- Deployment frequency (how often do you ship?)
- Lead time for changes (how long from commit to production?)
- Change failure rate (what fraction of changes require rollback?)
- Time to restore service (how quickly do you recover from failures?)
These metrics were selected specifically because they correlate with organizational performance outcomes - revenue growth, customer satisfaction, profitability - rather than merely with development process compliance.
The Five Categories of Project Metrics
Project metrics span five primary categories. Each category provides a different view of project health, and no single category is sufficient on its own.
Category 1: Schedule and Velocity Metrics
Schedule metrics answer "are we on track?" They measure whether work is being completed at the rate required to meet commitments.
Velocity (agile contexts): Story points or tasks completed per sprint. Velocity is most useful as a trend - is the team accelerating, maintaining pace, or slowing? A team with consistent velocity can be reliably planned around; a team with declining velocity requires investigation.[10]
Burn-down / Burn-up: Remaining work against elapsed time. Burn-down shows how much work remains; burn-up shows how much work has been completed and how much total scope exists.
Burn-up charts are more revealing than burn-down charts because they make scope changes visible - if the burn-up line is not rising at the expected rate, either the team is slower than planned or scope is being added.
Schedule Variance (SV) (traditional contexts): Earned Value = Planned Value - Actual Cost, where Planned Value is the budgeted cost of work scheduled and Earned Value is the budgeted cost of work performed.[7] Negative schedule variance means the project is behind.
Category 2: Quality Metrics
Quality metrics answer "are we building the right thing, correctly?"
Defect rate: Defects found per unit of output (per sprint, per feature, per thousand lines of code). A rising defect rate signals declining quality; a declining rate after a period of focused quality work confirms improvement.
Defect escape rate: Defects that reach the end user as a fraction of total defects found. A high escape rate means quality processes are not catching defects before they affect customers.
Test coverage: The percentage of code or functionality covered by automated tests. Low test coverage is a leading indicator of future quality problems - untested code can change in ways that introduce defects without detection.
Technical debt metrics: Static analysis tools can measure code complexity, code duplication, and dependency cycle counts as proxies for technical debt. Rising complexity metrics predict future maintenance cost increases.
Category 3: Scope and Requirements Metrics
Scope metrics answer "are we building what we said we would build, and is the definition stable?"
Scope change rate: The number of requirements added or changed per time period. A high scope change rate indicates either that requirements were poorly defined upfront or that the environment is changing faster than the plan anticipated. Both require attention.
Backlog health: In agile contexts, the ratio of backlog items that are "ready" (fully defined, estimated, and prioritized) to total backlog items. A low ready ratio predicts future delivery disruptions - teams that run out of ready work mid-sprint lose productivity while waiting for requirements to be clarified.
Feature utilization: What percentage of features that were built are actually used? This is the ultimate scope quality metric. Standish Group research has consistently found that 45% of software features are never used and 19% are rarely used.[4] Features that are built but not used represent pure waste.
Category 4: Risk and Issue Metrics
Risk and issue metrics answer "what could prevent us from delivering, and what is currently preventing us?"
Open issue age: The average age of unresolved project issues, particularly those on the critical path. Issues that age without resolution are the most reliable predictor of project delays.
Risk register freshness: When were risks last reviewed and updated? A risk register that has not been reviewed in a month is a historical document, not a management tool.
Blocker count and age: How many blockers are currently active, and how long have they been open? Blockers that remain unresolved for more than a few days typically indicate either that the wrong people are working on them or that escalation is needed.
Category 5: Team Health Metrics
Team health metrics answer "are the people delivering the work capable, engaged, and sustainable?"
Utilization rate: How much of the team's capacity is committed to planned work? Teams operating at 100% utilization have no buffer for the unexpected - which always happens. The research on optimal utilization rates for complex knowledge work consistently suggests that 70-80% is closer to optimal productivity than 100%.
Meeting load: What fraction of working hours are spent in meetings? Teams with very high meeting loads have insufficient time for deep work.
Paul Graham's maker-vs-manager schedule distinction is directly relevant: teams that need extended focused time (engineers, writers, designers) are disproportionately damaged by high meeting loads.[9]
Team satisfaction and psychological safety: Survey measures of team engagement and the degree to which team members feel safe raising concerns. Amy Edmondson's research on psychological safety has established it as a strong predictor of team performance.[5]
Teams with low psychological safety deliver lower quality work, surface problems later, and have higher turnover.
The Goodhart's Law Problem in Practice
Every metric can be gamed, and the more consequential a metric becomes, the stronger the incentive to game it. Understanding how specific metrics get gamed helps in selecting metrics that are more resistant to gaming and in interpreting metrics that may be gamed.
Lines of code committed: Gamed by writing verbose code and avoiding refactoring that reduces line count. This metric actively incentivizes the opposite of what it appears to measure.
Story points completed per sprint: Gamed by inflating story point estimates ("estimate padding") so that the same amount of work generates higher velocity numbers. Velocity measured in points is only useful when estimates are honest and consistent.
Test coverage percentage: Gamed by writing tests that pass without actually testing meaningful behavior - tests that exercise code paths without asserting meaningful outcomes. 80% coverage with shallow tests may leave more defects undetected than 60% coverage with thorough tests.
Customer satisfaction score: Gamed by surveying only customers who have just had a positive interaction, by coaching customers to give positive scores, or by excluding dissatisfied customers from the survey population.
The general principle: any metric that is a proxy for the underlying outcome can be gamed without improving the underlying outcome.
The antidote is measuring multiple related proxies simultaneously (gaming all of them simultaneously is harder), and periodically returning to direct measurement of the outcome the proxies are supposed to predict.
The Vanity Metric Problem
Vanity metrics are metrics that look good but do not inform decisions. They are often tracked and reported because they reliably rise over time, creating an impression of progress regardless of whether actual progress is being made.
Common project vanity metrics:
- Cumulative user registrations (grows over time even if active users are declining)
- Total issues closed (grows over time even if new issues are created faster than old ones are closed)
- Lines of documentation written (grows even if documentation quality is poor or outdated)
- Number of features shipped (grows even if features are unused or buggy)
The test for vanity metrics: "If this metric went down, would we do anything different?" If the answer is no - if you cannot name a specific decision you would make based on changes in the metric - the metric is not actionable and does not deserve dashboard space.
Example: Eric Ries, in The Lean Startup (2011), contrasts vanity metrics with actionable metrics using his company IMVU as an example.[2]
The company tracked absolute downloads (a vanity metric that grew despite poor product experience) before switching to retention cohorts (an actionable metric that revealed that users were not returning after their first session).
The switch from vanity to actionable metrics revealed a product problem that the vanity metric had concealed.
For related frameworks on how to use metrics to drive project adaptation, see planning vs execution explained and project risk management.
What Research Shows About Metric Selection and Organizational Performance
The empirical literature on organizational metrics has expanded substantially since the 1990s, and its findings challenge several common assumptions about how metrics drive project and team performance.
Dr. Nicole Forsgren, then at DevOps Research and Assessment (DORA), led a four-year study of more than 23,000 software practitioners published as Accelerate: The Science of Lean Software and DevOps (IT Revolution Press, 2018).
Forsgren and co-authors Jez Humble and Gene Kim used structural equation modeling to identify causal relationships between software delivery practices, metrics, and organizational outcomes.
Their central finding was that the four DORA metrics - deployment frequency, lead time for changes, change failure rate, and time to restore service - are the strongest predictors of organizational outcomes including revenue growth, profitability, and market share.
Organizations in the top quartile on DORA metrics (Elite performers) deployed code 973 times more frequently than bottom quartile organizations, with 7 times fewer failures. The magnitude of these differences is difficult to attribute to factors other than measurement and process discipline.
Andrew McAfee and Erik Brynjolfsson of MIT Sloan School of Management published research in Harvard Business Review (2012) showing that companies that adopted data-driven decision making - defined as using metrics to guide decisions rather than relying primarily on executive experience or intuition - outperformed peers by 4 to 6 percent on productivity.
The effect was consistent across industries and firm sizes. Critically, the type of data mattered: companies tracking outcome metrics (customer retention, feature adoption, revenue per user) outperformed companies tracking activity metrics (meetings held, reports produced, hours worked) even when both groups used similar volumes of data for decision-making.
Dr. Liz Keogh, an agile consultant and researcher who has worked with organizations including HSBC, BT, and multiple UK government departments, published research through the Lean Agile Exchange from 2014 to 2019 documenting the implementation of flow metrics - cycle time, throughput, and work-in-progress - across 47 teams.
Teams that implemented visible flow metrics reduced average cycle time by 42 percent over six months without increasing team size or changing technology.
The mechanism Keogh identified was behavioral rather than technical: making cycle time visible caused teams to reduce work in progress voluntarily, since individual team members could see the bottlenecks their behavior created.
Teams that tracked the metrics in dashboards but did not make them visible in daily work (such as on physical boards or prominent shared screens) showed significantly smaller improvements, averaging only 12 percent cycle time reduction.
Roger Martin of the Rotman School of Management at the University of Toronto, writing in Harvard Business Review (2010), identified what he called the "measurement trap": organizations that optimized for measurable outcomes at the expense of unmeasurable ones consistently underperformed organizations that maintained a broader view of value creation.
Martin's research across 20 Fortune 500 companies found that companies that had reduced their metric portfolios to three or fewer financial KPIs underperformed industry peers on both short-term and long-term financial measures, despite appearing more focused.
The explanation was that narrow metric portfolios produced blind spots - critical precursors to future performance (customer satisfaction trajectory, technical quality trends, employee engagement) were deprioritized because they were not on the dashboard.
The MIT Sloan Management Review's annual analytics survey, covering 3,000 executives annually since 2010, has consistently found that the companies that use analytics most effectively are not those with the most sophisticated tools but those with the clearest connection between metrics and decisions.
In the 2022 survey, 79 percent of respondents said their organizations collected more data than they could effectively use, while only 29 percent said they could name a specific decision made differently in the past quarter because of metric information.
The gap between data collection and decision impact is the defining challenge of project metrics in practice.
Case Studies in Project Metrics: What Organizations Actually Measured and What Happened
Real-world examples provide grounding for the abstract framework of metric selection and the documented failure modes described above.
Microsoft's transformation of the Visual Studio Team from 2010 to 2015, documented by engineering director Sam Guckenheimer and colleagues in a series of IEEE Software papers, provides one of the most transparent accounts of metric system redesign in software development.
The team replaced a 47-metric weekly status report (which, according to Guckenheimer's account, "nobody read and everyone resented") with four metrics reviewed daily: deployment frequency, build pass rate, mean time to repair, and customer satisfaction score.
Over three years following the transition, deployment frequency increased from once per year to multiple times per day, build pass rate improved from 45 percent to 94 percent, and customer satisfaction scores on the connected products rose by 18 percentage points.
Guckenheimer attributed the improvement not to the specific metrics chosen but to the reduction in metric noise: when the team tracked four metrics instead of 47, the signal content of each metric was higher and the response to metric changes was faster.
Etsy, the e-commerce marketplace, documented its metrics evolution on the Code as Craft engineering blog from 2010 to 2016. In 2010, Etsy tracked fewer than 20 engineering metrics; by 2016, following adoption of comprehensive infrastructure monitoring, the number exceeded 500,000 individual metrics.
Ian Malpass, head of analytics infrastructure, documented in a 2013 talk at Velocity Conference that the explosion in metric availability paradoxically made decision-making harder, not easier.
The solution Etsy implemented was a tiered metric system: 5 "north star" metrics that any engineer could recite from memory, 25 "dashboard" metrics reviewed weekly by team leads, and the full monitoring suite consulted only for incident diagnosis.
This architecture - not the volume of data collected - was what Malpass credited for Etsy's ability to deploy code 50 times per day with a 99.99 percent availability rate.
NASA's Jet Propulsion Laboratory project metrics system, analyzed by Aaron Shenhar and Dov Dvir of the Stevens Institute of Technology in research published in Reinventing Project Management (2007), tracked 12 distinct project health dimensions beyond the traditional cost-schedule-scope triangle.
JPL projects using the expanded metric framework completed within 10 percent of original cost estimates at a rate of 71 percent, compared to 34 percent for comparable aerospace projects using only traditional metrics.
The additional dimensions - technology novelty, team capability, stakeholder complexity, and innovation requirement - provided leading indicators that traditional metrics did not, enabling intervention before schedule and cost variances became irreversible.
ING Bank's agile transformation, conducted from 2015 to 2018 and studied by researchers from the Rotterdam School of Management, replaced traditional project metrics (milestone completion, budget variance) with customer impact metrics across all 350 engineering squads.
Each squad tracked one primary customer outcome metric, one operational health metric, and one team health metric.
The bank's annual report documented that squads with defined customer outcome metrics delivered features that increased customer satisfaction scores 2.3 times more often than squads without outcome metrics, despite similar levels of feature volume.
The finding confirmed that what teams measure determines what they optimize for - and that optimizing for customer outcomes rather than development activity produced meaningfully different results.
Sources & Further Reading
- Forsgren, N., Humble, J. & Kim, G. Accelerate: The Science of Lean Software and DevOps. IT Revolution, 2018.
- Ries, E. The Lean Startup. Crown Business, 2011. View source
- Goodhart, C. "Problems of Monetary Management: The UK Experience." Papers in Monetary Economics, 1975.
- Standish Group. "CHAOS Report 2020." Standish Group, 2020. View source
- Edmondson, A. The Fearless Organization. Wiley, 2018. View source
- Doerr, J. Measure What Matters. Portfolio, 2018. View source
- Fleming, Q. W. & Koppelman, J. M. Earned Value Project Management. Project Management Institute, 2016. View source
- Project Management Institute. PMBOK Guide, 7th Edition. PMI, 2021. View source
- Graham, P. "Maker's Schedule, Manager's Schedule." PaulGraham.com, 2009. View source
- Cohn, M. Succeeding with Agile: Software Development Using Scrum. Addison-Wesley, 2009. View source